AI Workflows · Guide
Build a Human Review Loop for AI-Generated Work
Design review around consequences, evidence, and clear ownership so AI output can move quickly without quietly becoming the final decision.
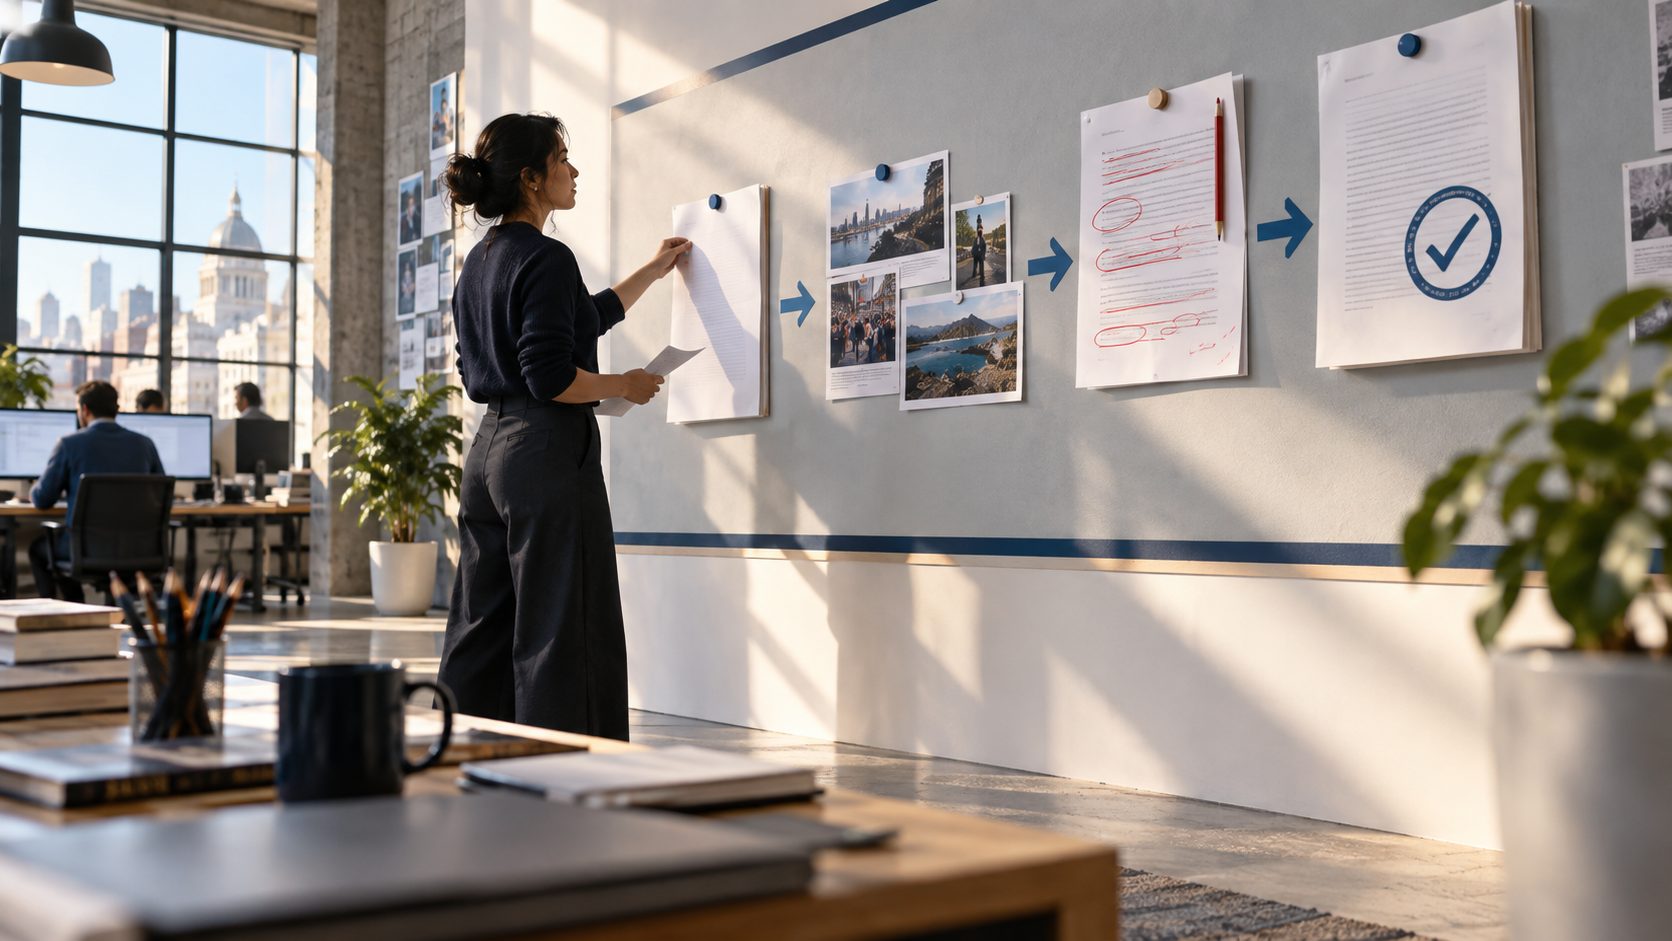
A useful human review loop assigns AI a bounded drafting role, routes each output according to risk, gives reviewers the source material and acceptance criteria they need, and records who approved the result. The goal is not to inspect every sentence with equal effort; it is to place meaningful review where an error would change a decision, harm a person, or mislead an audience.
Start with the consequence, not the model
A review process becomes vague when it begins with a model name or a blanket instruction to “check the AI.” Begin with the work that will happen after the output. A private brainstorming note has a different consequence from a customer email, a hiring recommendation, a pricing comparison, or a public health claim. Write the intended use in one sentence and name the person affected by an error. Then ask what kind of error matters: a false fact, a missing exception, a disclosure of confidential material, an unfair recommendation, an unusable format, or a decision made without authority. This framing prevents two common failures. The first is spending expensive expert time on harmless drafts. The second is letting polished high-consequence output pass because it looks routine. NIST’s AI RMF treats context, intended use, expected benefits, costs, and human oversight as things to define and document. A small team can apply that logic without creating a governance department.
- Name the user and downstream action.
- Describe the most important failure in ordinary language.
- Decide whether the output is advice, a draft, evidence, or an action request.
Create three practical review lanes
Use a small routing system. A low-consequence lane covers reversible internal work such as alternative headings, rough summaries, or an agenda draft. The owner can check task fit and obvious errors. A standard lane covers material that informs colleagues or customers but remains reviewable before release. It needs source checks, policy checks where relevant, and a named approver. A high-consequence lane covers work that affects rights, money, safety, employment, legal obligations, security, or people who cannot easily correct the result. That lane should not be “more careful prompting.” It should require the accountable subject-matter owner, approved tools and data, documented evidence, and a stop rule when the necessary expertise is unavailable. Routing is about the job, not about how confident the model sounds. The same model output may be low consequence as a private outline and high consequence when copied into a final decision.
- Low: reversible, private, easy to verify.
- Standard: external or operational, reviewed before use.
- High: material consequences, specialist approval, fail closed.
Give the reviewer an evidence packet
A reviewer cannot validate an answer if they see only the answer. Keep the assignment, approved source excerpts, relevant policy, model output, and open questions together. For factual material, identify which sentences are supported by which sources and when those sources were checked. For a transformation task, preserve the original input so the reviewer can detect omissions or altered meaning. For classification or extraction, include representative examples and expected results. For creative work, include the brief and prohibited elements. The packet should be smaller than the project archive. It exists to let a reviewer answer three questions quickly: did the output perform the requested task, is the important evidence inspectable, and did it stay inside the permitted boundary? If source access is missing, mark the result unresolved instead of asking the reviewer to approve a fluent guess.
- Keep the original input beside the output.
- Link claims to current source material.
- Separate unresolved questions from requested stylistic edits.
Write acceptance criteria before generation
“Looks good” is not a review standard. Define a few observable checks before the tool runs. A research summary might need every recommendation linked to a supplied source, uncertainty stated, and no invented quotation. A support reply might need the correct policy, no account-specific disclosure, a clear next step, and escalation when the policy does not answer the case. A translated article might need protected product terms, preserved numbers, target-locale fluency, and accurate language metadata. Criteria should cover both success and veto conditions. A response can be concise and still fail because it exposes a secret. It can be factually correct and still fail because it makes a decision the tool was not authorized to make. Writing the checks first also improves prompts: the model receives a real job and the human receives the same definition of done.
- Use four to seven observable criteria.
- Put veto conditions above preferences.
- Do not let a numeric score cancel a security or policy failure.
Separate author, reviewer, and approver decisions
On a small team, one person may hold several roles, but the roles should still be visible. The author owns the request and source packet. The reviewer examines the output against the criteria and records changes. The approver accepts the residual risk and authorizes the downstream use. For low-risk work, author and reviewer may be the same person. For material claims or external commitments, a second perspective reduces the chance that the person who framed the request also overlooks the same assumption in the answer. NIST’s guidance emphasizes defined responsibilities for human-AI configurations and oversight. The practical version is a byline in the record: drafted with AI assistance, reviewed by a named owner, approved for a specific use on a specific date. This is not a claim that the output is permanently correct. It is evidence that someone accountable made the decision.
- Name the role even when one person holds two roles.
- Require a separate approver when policy or consequence demands it.
- Approve a defined use, not a universal truth.
Review in the right order
First check boundary and safety: was approved data used, did the output stay within the requested task, and are there instructions or embedded content that could have redirected the workflow? OWASP’s guidance on prompt injection, sensitive information disclosure, and improper output handling is a reminder that generated text is untrusted input, not executable authority. Second check factual integrity against the evidence packet. Third check completeness: important exceptions, affected users, and escalation paths. Fourth check usefulness and tone. Polishing first is dangerous because a clear sentence can make a weak claim feel settled. Use comments that identify the failure and the fix: “source does not support this date,” “policy owner must answer,” or “remove this customer detail.” Avoid the unhelpful instruction to “make it safer” without saying what must change.
- Boundary and data first.
- Evidence and omissions second.
- Clarity and style only after the decision is sound.
Make revision a controlled loop
When a draft fails, send back the smallest useful correction. Attach the failed criterion, the relevant source, and the expected change. Do not silently replace the source packet or ask the model to regenerate everything when one paragraph is wrong. A full reroll makes it difficult to see whether a repaired claim caused a new omission elsewhere. For important work, compare revisions with a diff or a short change summary. Limit the number of automated repair attempts; repeated failure is evidence that the task, data, or tool is a poor fit. The human owner can then rewrite the section, narrow the use, choose a different method, or stop. A stop is a valid outcome. The review loop exists to manage the work, not to guarantee that every generated draft reaches publication.
- Return the failed criterion with the revision request.
- Change one bounded area when possible.
- Escalate repeated failure instead of hiding it with more generations.
Keep a decision record that can be audited
Record the output version, intended use, sources, reviewer, changes, approval, and expiry or review trigger. The record can be a short table or an issue comment; it does not need a new platform. Store only what policy permits. If the input contains personal or confidential data, the review record should reference an approved location rather than duplicating the material. Include the limits of the review: perhaps the editor checked citations and tone but did not validate a legal interpretation. This prevents an approval badge from acquiring more meaning than it deserves. When the source, model, policy, or use changes, reopen only the affected checks. A lightweight record saves the next reviewer from reconstructing a decision from chat history.
- Record what was checked and what was not.
- Add a review trigger for volatile claims or changed use.
- Keep sensitive evidence in its approved system.
Measure whether review improves the workflow
Track a few signals that connect to the job: serious errors caught before use, reviewer minutes, common failure types, percentage of outputs routed to escalation, and rework after approval. Do not treat acceptance rate as the only success metric. A system that approves everything may have weak tests; a system that rejects everything may be using AI for the wrong task. Sample approved outputs periodically, especially after a model or prompt change. Invite feedback from the people who receive the result, not only the people who operate the tool. The aim is a stable division of labor: AI reduces bounded drafting effort, reviewers focus on meaningful judgment, and accountable owners remain in control of consequential decisions. If the review cost consistently exceeds the benefit, narrow or retire the workflow.
Example: review a public tool comparison
Imagine an editor uses AI to organize notes for a comparison of two workplace tools. The intended output is a public guide, so the editor routes it to the standard lane. The evidence packet contains current product documentation, a pricing-page capture date, the comparison brief, and a note that the team has not performed a long-term hands-on test. Acceptance criteria require plan-specific claims to link to official pages, prohibit invented testing language, and require unresolved privacy questions to remain unresolved. The model drafts a clean table but merges a free-plan limit from one product with the paid plan of another. The reviewer catches the mismatch because the claims remain connected to their source excerpts. The correction request names the row, source, and expected plan label; it does not regenerate the entire article. A second reviewer checks the recommendation and sees that the operational conclusion still depends on an administrator confirming a retention setting. The article is approved only with that dependency visible. The record states which pages were checked, which claims were not independently tested, who reviewed the comparison, and when price-sensitive facts should be revisited. This is a strong review loop because it produces a useful, bounded result without upgrading a drafting tool into an authority.
Use the smallest loop that controls the risk
Do not add a committee where one accountable editor and a checklist are enough. Add specialist review only for the questions that require it. A simple lane, evidence packet, criteria, owner, and record can control most editorial drafting work. Complexity should follow consequence, not enthusiasm for process.
Keep the handoff visible
Place the current status where the next person already works: waiting for evidence, ready for review, returned for revision, approved for a named use, or stopped. Avoid an ambiguous “done” label that could mean the model finished rather than a person approved the result. The handoff should identify the owner and the next permitted action. If a draft is copied into another system, carry the review status with it so presentation quality cannot be mistaken for authorization. This small operational detail closes the gap between a sound checklist and the moment someone actually uses the output.
Sources and update note
Follow the linked official source before a product, price, plan, or policy decision.