AI Tool Decisions · Guide
Evaluate AI Document Extraction Tools With a Grounded Test Set
Compare document tools on the fields, layouts, exceptions, and review costs your workflow actually contains.
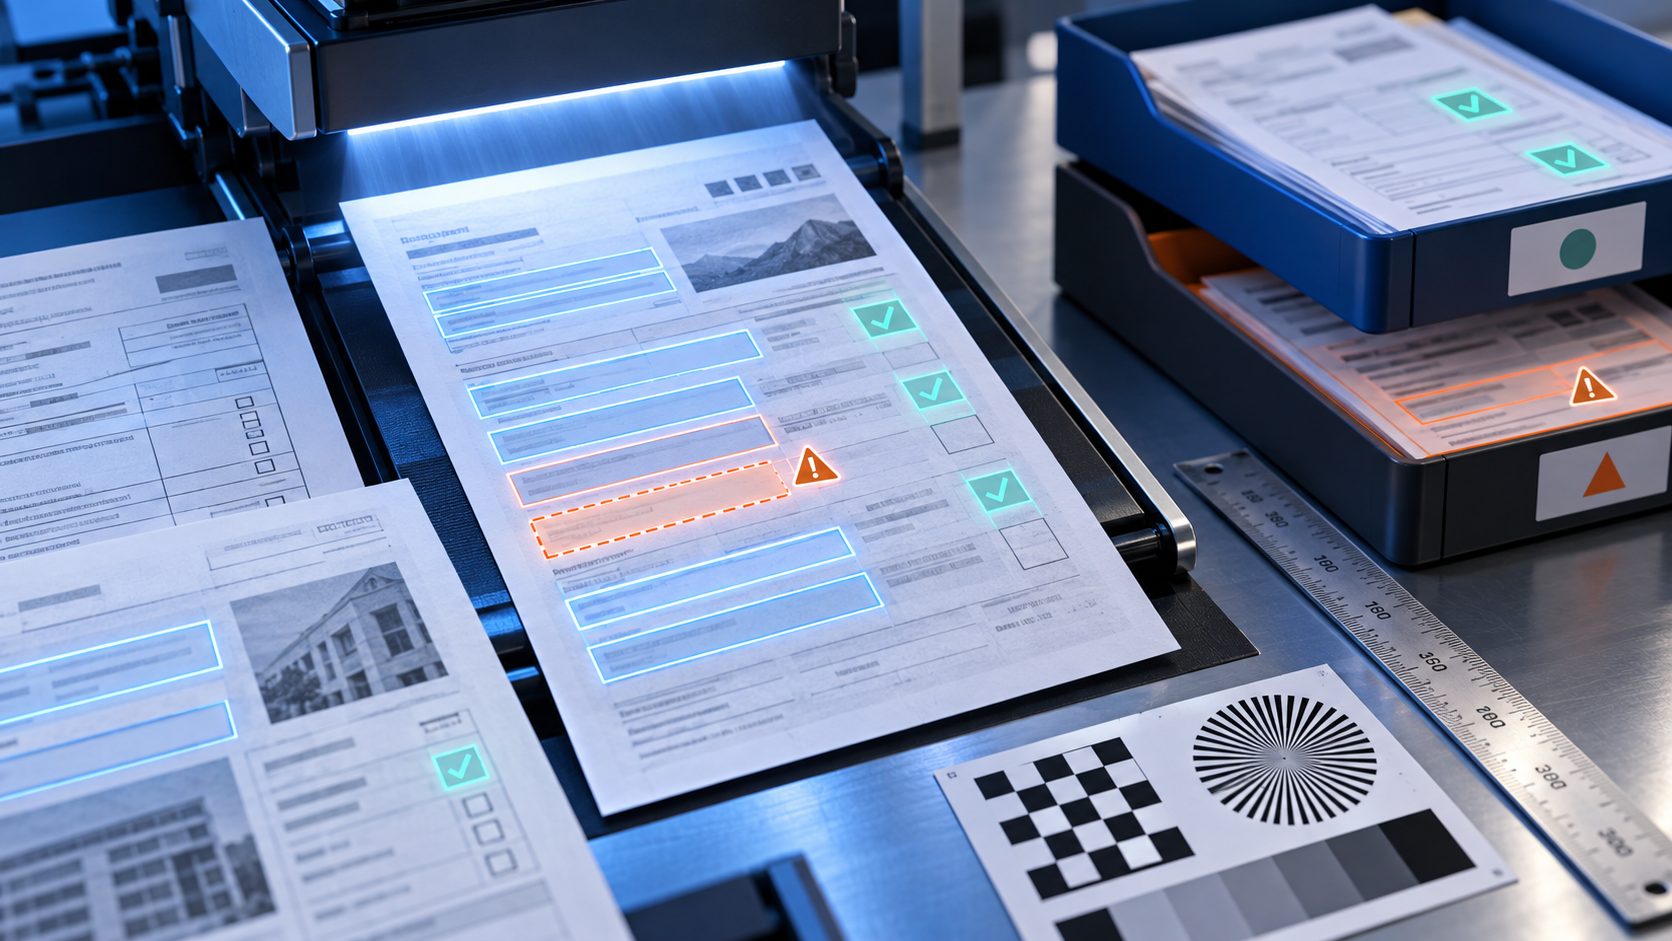
Evaluate extraction with labeled representative documents and field-level acceptance rules. Measure false positives, false negatives, formatting errors, exception handling, and human correction time; do not choose a tool from one clean demo document or a single confidence score.
Define the extraction job
List the document types, required fields, downstream use, volume, languages, handwriting, tables, checkboxes, and image quality you expect. Separate “nice to capture” from fields that control payment, identity, routing, or compliance. Decide whether the tool must classify, split, OCR, extract, normalize, or all five. A generic demo can look accurate while solving a different task. Your test should answer whether the system produces usable structured data for the actual next step.
- Name required fields.
- Collect real layout variants.
- Describe the downstream action and consequence.
Create a labeled test set
Select permitted examples across common and difficult cases: clean digital files, scans, rotated pages, optional fields, repeated line items, unfamiliar templates, and blank values. Label the expected field name and value, including when no value should be returned. Keep training and test examples separate if the tool is configurable. The test set does not need to be huge to expose basic failure patterns, but it must represent the work rather than the easiest documents. Protect personal and confidential data through approved storage and access.
- Include absence as an expected result.
- Preserve document and label versions.
- Do not upload sensitive samples before approval.
Read precision and recall in context
Precision asks how many predicted entities matched the annotations; recall asks how many annotated entities the tool found. A high-recall system may create more false positives, while a high-precision threshold may miss valid values. Google’s Document AI documentation also explains why one aggregate accuracy number can be misleading when fields are optional or repeat. Review metrics per critical label and inspect actual false positives and false negatives. A missed invoice total is not equivalent to a missed optional note. Choose thresholds from the cost of each error and route uncertain cases to review.
- Review critical fields separately.
- Inspect examples behind aggregate metrics.
- Set thresholds from error consequences.
Test normalization and structure
An extracted string can be textually close and operationally wrong. Check dates, decimal separators, currencies, signs, units, addresses, names, identifiers, and table row relationships. Verify that repeated fields remain attached to the correct line item and that page boundaries do not merge unrelated values. Compare both raw text and normalized value when the product provides them. If fuzzy matching is used in evaluation, understand what differences it accepts. Downstream systems should validate type and range rather than trusting a confidence value as permission to write.
- Validate types and ranges.
- Keep table relationships.
- Test locale-specific formats.
Measure the review workflow
Give reviewers the prediction, source region, confidence where useful, and a fast correction path. Measure how long they spend finding and fixing important errors. A product that extracts more fields can still be slower if reviewers cannot locate the source. Test how exceptions are exported, who can approve corrections, and whether the final value remains linked to the document. Do not silently auto-accept because confidence exceeds a vendor default. Set a policy for straight-through processing only after the test set shows the field and document class behave within the team’s tolerance.
- Measure correction time.
- Keep source context visible.
- Require approval for consequential writes.
Run a production-shaped pilot
Process a bounded batch without changing the authoritative system automatically. Compare tool output with the labeled result and the existing manual workflow. Record failed files, unsupported formats, latency, cost, review time, and operational friction. Monitor drift when document templates or processor versions change. The decision record should name the approved document classes, fields, thresholds, review rule, owner, and reevaluation trigger. A tool can be approved for one stable form and rejected for a mixed inbox; that narrow result is more useful than declaring a universal winner.
Compare vendors with the same packet
Give every candidate the same permitted documents, schema, field definitions, and acceptance rules. Use current official documentation to record file limits, supported languages, processor version, region, security controls, and pricing assumptions for the exact service. Do not give one tool a hand-cleaned sample and another the messy original. Review exports as well as the user interface: the downstream JSON or table may reveal missing page references, unstable field names, or nested values that are difficult to use. Keep product-specific setup separate from the shared scorecard so a future tool can enter the same evaluation without rewriting the business requirements.
Plan exception handling before automation
Define what happens when a file is unreadable, a required field is absent, a confidence threshold is missed, or two values conflict. Route the document to a person with the source and reason; do not silently substitute an empty string or previous value. Prevent repeated retries from creating duplicate records. Keep the authoritative system unchanged until a validated result and permitted reviewer action are available. Measure the exception rate by document class. If a rare layout creates most of the review work, exclude that class or create a separate process rather than weakening the rule for every document.
Use a weighted decision without hiding vetoes
Create separate scores for critical-field quality, layout coverage, review experience, integration, controls, cost, and support. Weight them according to the workflow, but place veto conditions outside the total. A tool that exposes prohibited data, cannot preserve source references, or cannot route a critical exception is not rescued by a high average score. Write the evidence beside each score and mark unknown values. Invite the people who correct documents and maintain the integration to review the result. Their time and failure experience often change the ranking more than an attractive demo interface.
Recheck after meaningful change
Keep a frozen sample of the permitted test set and rerun affected cases after a processor, schema, threshold, or document template changes. Compare by field and document class, not only by a new aggregate score. If the vendor updates a pretrained model automatically, record the observed version or date and sample production output before expanding use. A stable review queue and rollback path matter as much as the first evaluation. The best tool choice is one the team can monitor and correct when the environment moves.
Estimate cost from reviewed documents
Calculate cost per accepted document, not only price per page or API request. Include classification, extraction, storage, retries, review time, exception handling, integration support, and any minimum plan charge. Separate normal documents from exception-heavy classes so a high average does not hide one expensive format. Use a low, expected, and high volume scenario rather than a precise annual forecast from a small test. If a vendor price depends on processor type or committed volume, record the current assumption and date. The comparison should show which cost changes when volume grows and which remains fixed.
Prepare a decision packet another team can repeat
Package the schema, label definitions, permitted test manifest, scoring method, raw results, reviewer notes, product configuration, and decision record. Do not include sensitive source files in a broadly shared report; link to controlled storage. A colleague should be able to rerun the evaluation after a product change without guessing which threshold or field definition was used. Note known gaps, such as an unsupported language or too few handwritten samples. Reproducibility keeps the evaluation useful after the people who ran the first test move on.
Sources and update note
Follow the linked official source before a product, price, plan, or policy decision.